This page covers state-space representation and uninformed (blind) search. It continues in Informed Search, Local Search & Genetic Algorithms, which covers heuristic search (Greedy, A*), local search (Hill Climbing, Simulated Annealing, Tabu Search), and Genetic Algorithms.
2.1 Introduction
Search is one of the most fundamental problem-solving techniques in artificial intelligence. Many AI problems can be formulated as finding a sequence of actions that transforms an initial state into a goal state.
Core Concept
The goal of an agent is to:
Start from an initial state
Perform a sequence of actions
Reach a goal state (or a state with high desirability)
Two Main Scenarios
Goal-Oriented Search: Find a path from start to goal
Example: Solving a maze, solving a puzzle
Cost may be associated with paths
Optimization Search: Find state with minimal loss
Example: Eight-queens placement, scheduling
Cost is associated with states themselves
Applications
Why Search Matters
No Direct Formula: Many problems have no closed-form solution
Large Solution Space: Too many possibilities to enumerate
Need Systematic Methods: Avoid aimless wandering
Trade-offs: Different strategies balance time, memory, and solution quality
2.1.1 State Space as a Graph
Modeling the state space as a directed graph enables systematic search:
Key Concepts:
Node: Represents a state
Edge: Represents a transition (action) from one state to another
Path: Sequence of edges from initial state to goal
Example: Eight-Queens Problem
Problem: Place 8 queens on a chessboard so none attack each other.
State Space Design:
Approach 1 (Incremental):
State: Placement of k ≤ 8 queens (no attacks)
Action: Add one more queen
Initial State: Empty board (k=0)
Goal State: 8 queens placed (k=8)
Graph Type: Directed Acyclic Graph (DAG)
Approach 2 (Complete State):
State: Any placement of 8 queens (attacks allowed)
Action: Move one queen to different square
Initial State: Random placement
Goal State: No attacks
Graph Type: Undirected graph with cycles
State Space Size
| Problem | State Space Size |
|---|---|
| 8-Queens (any placement) | 64C8 ≈ 4.4 × 10⁸ |
| 8-Puzzle | 9! = 362,880 |
| Chess (valid positions) | > 10⁴³ |
| Rubik’s Cube | ≈ 4.3 × 10¹⁹ |
2.1.2 Search Space vs Search Tree
The state space graph represents all possible states and transitions in the problem domain, while the search tree represents the specific paths taken during the search process.
Key Differences:
| Aspect | State Space Graph | Search Tree |
|---|---|---|
| Definition | All possible states and transitions | Paths explored by search algorithm |
| Duplicates | Each state appears once | Same state may appear multiple times |
| Size | Fixed by problem | Can be infinitely larger |
| Cycles | May contain cycles | Represents unrolled paths |
Example: State Space Graph
Corresponding Search Tree:
The search tree unfolds paths from the root, potentially duplicating states reached via different paths.
Example with Cycles:
Consider a graph:
State Space: 4 nodes (S, a, b, G)
Search Tree: Could expand infinitely
This is why search algorithms must track visited states to avoid infinite loops!
2.1.3 Search Problem Examples
Example 1: Pacman
Problem: Navigate Pacman through a maze to collect all food pellets.

State Space Design:
State: Pacman’s current position + remaining food pellets
Successor Function: Moving in one of four cardinal directions (N, E, S, W)
Start State: Pacman at initial position with all food pellets present
Goal Test: All food pellets have been collected
Example 2: Traveling in Romania
Problem: Find the shortest route between cities.

State Space Design:
State: Current city location
Successor Function: Moving from one city to another connected by a road (cost = distance)
Start State: Initial city (e.g., Arad)
Goal Test: Reaching destination city (e.g., Bucharest)
Example 3: Eight-Puzzle
Problem: The Eight-Puzzle is a sliding puzzle that consists of a 3x3 grid with eight numbered tiles and one empty space. The objective is to arrange the tiles in a specific order by sliding them into the empty space.
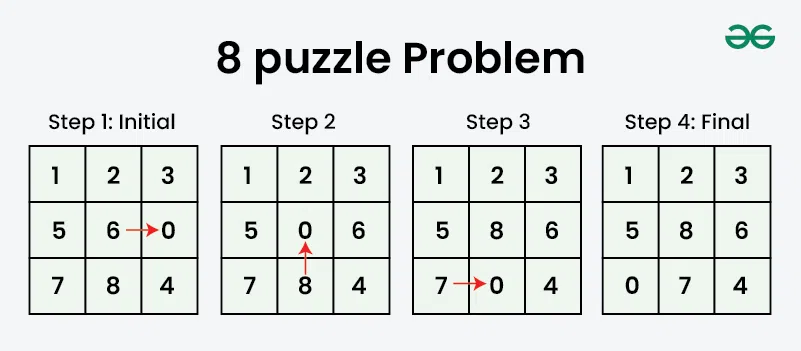

State Space Design:
State: Configuration of tiles on the 3×3 board
Successor Function: Sliding a tile into the empty space
Start State: Initial scrambled configuration
Goal Test: Tiles arranged in desired order (1-8 with blank in corner)
Example 4: Online Maze Search

State Space Design:
State: Agent’s current position in the maze
Successor Function: Moving in one of four cardinal directions (up, down, left, right) based on current position and maze layout
Start State: Initial position in the maze
Goal Test: Reaching the exit of the maze
2.2 Uninformed Search Algorithms
Uninformed search algorithms, also known as blind search algorithms, are a category of search strategies that operate without any domain-specific knowledge about the problem being solved. They explore the search space systematically, relying solely on the structure of the state space and the goal test to find a solution.
Generic Search Framework
All uninformed search algorithms follow this template:
Algorithm: GenericSearch(Initial State s, Goal Condition G)
Input: Initial state s, Goal condition G
Output: Path from s to goal, or failure

begin
    LIST ← {s}              // Frontier nodes to explore
    VISIT ← ∅               // Visited nodes
    pred ← empty array      // Predecessor tracking

    repeat
        if LIST is empty then
            return failure

        // Selection strategy differs by algorithm
        Select node i from LIST
        Delete i from LIST
        Add i to VISIT

        if i satisfies G then
            return reconstruct_path(pred, s, i)

        // Expand node i
        for each node j adjacent to i do
            if j not in VISIT and j not in LIST then
                Add j to LIST
                pred[j] ← i
    until LIST is empty or goal found
end
Key Components:
LIST: Frontier nodes (boundary of explored region)
VISIT: Already explored nodes
pred: Predecessor array to reconstruct path
Selection Strategy: Determines which algorithm we get
2.2.1 Breadth-First Search (BFS)
BFS explores nodes level by level, visiting all nodes at depth d before any node at depth d+1.
Selection Strategy: FIFO queue (First-In-First-Out)
How it works:
Start with initial state in queue
Remove first node from queue
Check if it’s a goal
Add all unvisited neighbors to end of queue
Repeat
BFS Exploration Pattern:
Properties:
| Property | Value | Explanation |
|---|---|---|
| Complete | Yes | Will find solution if one exists |
| Optimal | Yes* | Finds shallowest (shortest path) goal |
| Time Complexity | O(b^d) | Exponential in depth |
| Space Complexity | O(b^d) | Must store entire frontier |
*Only when all actions have equal cost
Where:
b: branching factor (average number of successors)
d: depth of shallowest goal
Advantages:
Guaranteed to find solution
Finds shortest path (minimum edges)
Disadvantages:
Memory intensive: Must store all nodes at current level
Slow for deep goals
2.2.2 Depth-First Search (DFS)
DFS explores as deep as possible along each branch before backtracking.
Selection Strategy: LIFO stack (Last-In-First-Out)
How it works:
Start with initial state on stack
Pop top node from stack
Check if it’s a goal
Push all unvisited neighbors onto stack
Repeat
DFS Exploration Pattern:
Properties:
| Property | Value | Explanation |
|---|---|---|
| Complete | No | Can get stuck in infinite paths |
| Optimal | No | May find longer paths first |
| Time Complexity | O(b^m) | Can explore entire tree |
| Space Complexity | O(bm) | Only stores single path |
Where:
m: maximum depth of any node
Advantages:
Memory efficient: Only stores nodes on current path
Fast if solutions are deep
Disadvantages:
Can get stuck in infinite loops (needs cycle detection)
May find suboptimal solutions
Not complete in infinite spaces
Comparison: BFS vs DFS

| Aspect | BFS | DFS |
|---|---|---|
| Frontier Shape | Wide, shallow | Deep, narrow |
| Memory | O(b^d) - HIGH | O(bm) - LOW |
| Optimal | Yes (equal costs) | No |
| Complete | Yes | No (with cycles) |
| Best For | Shallow goals | Deep solutions, memory limited |
2.2.3 Uniform-Cost Search (UCS)
UCS generalizes BFS to handle weighted graphs where actions have different costs. It is an uninformed search algorithm that expands the least costly node first, ensuring that the path to the goal is optimal in terms of cost. It uses a priority queue to manage the frontier, where nodes are prioritized based on their cumulative cost from the start state.
Selection Strategy: Priority queue ordered by path cost g(n)
Key Idea: Always expand the node with the lowest cumulative path cost from start.
Path Cost: g(n) = sum of edge costs from start to node n
How it works:
Maintain priority queue of nodes, ordered by g(n)
Always expand node with smallest g(n)
Update costs when shorter paths are found
Detailed Example:
After UCS execution:
Properties:
| Property | Value |
|---|---|
| Complete | Yes |
| Optimal | Yes |
| Time Complexity | O(b^(C*/ε)) |
| Space Complexity | O(b^(C*/ε)) |
Where:
C*: cost of optimal solution
ε: minimum edge cost
2.2.5 Bidirectional Search
Run two simultaneous searches: one forward from start, one backward from goal. Stop when they meet.
Key Idea: Two small searches are faster than one large search.
Algorithm BiSearch(Initial State: s, Goal State: g)
 begin
	FLIST= { s }; BLIST= { g };
	repeat
		Select current node if from FLIST based on pre-defined strategy;
		Select current node ib from BLIST based on pre-defined strategy;
		Delete nodes if and ib respectively from FLIST and BLIST;
		Add nodes if and ib to the hash tables FVISIT and BVISIT, respectively;
		for each node j ∈ A(if) not in FVISIT reachable from if do
			Add j to FLIST; pred(j)=if;
		for each node j ∈ B(ib) not in BVISIT do
			Add j to BLIST; succ(j)=ib;
	until FLIST or BLIST is empty or (FLIST ∩ BLIST)= {};
	if (either FLIST or BLIST is empty) return failure;
		else return success;
	{ Reconstruct source-goal path by selecting any node in FLIST ∩ BLIST
	and tracing predecessor and successor lists from that node; }
 end
Complexity Improvement:
Normal BFS: O(b^d)
Bidirectional: O(2 × b^(d/2)) = O(b^(d/2))
Example: If b=10, d=6:
Normal: 10^6 = 1,000,000 nodes
Bidirectional: 2 × 10^3 = 2,000 nodes
Requirements:
Must be able to generate predecessors
Must be able to check if nodes from both searches match
Challenges:
Requires goal state to be explicitly known
Need to detect when searches meet
More complex implementation
Summary: Uninformed Search Algorithms
| Algorithm | Complete | Optimal | Time | Space | When to Use |
|---|---|---|---|---|---|
| BFS | Yes | Yes* | O(b^d) | O(b^d) | Shallow goals, all costs equal |
| DFS | No | No | O(b^m) | O(bm) | Memory limited, deep solutions |
| UCS | Yes | Yes | O(b^(C*/ε)) | O(b^(C*/ε)) | Weighted graphs |
| Bidirectional | Yes | Yes* | O(b^(d/2)) | O(b^(d/2)) | Know both start and goal |
*Optimal only for equal-cost actions